[精讚] [會員登入]
941

python+curl 爬資料(一)

“
需要某網站資料抓回來統計,結果當然沒我想的那麼簡單, 程式跑一跑就撈回來 光這裡就卡好久, 後來觀察cookie 從 c
„

分享此文連結 //n.sfs.tw/16452

分享連結 python+curl 爬資料(一)@igogo
(文章歡迎轉載,務必尊重版權註明連結來源)
2024-10-23 10:09:13 最後編修
2024-09-24 13:53:39 By igogo


需要某網站資料抓回來統計,結果當然沒我想的那麼簡單, 程式跑一跑就撈回來

光這裡就卡好久,  後來觀察cookie  從 cf_clearance 找到這篇文章
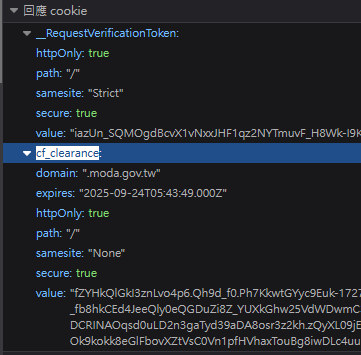


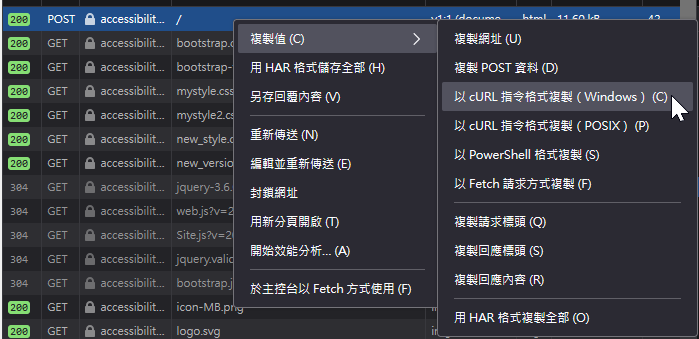
目前只能做到半自動, 使用firefox 建立session後

如圖複製cURL指令,產生bat檔 ,再執行bat,將3x 頁面抓回來解析


import re
 
#delete tmp files
for file in os.listdir('./tmp/'):
    if file.endswith(".html"):
        os.remove('./tmp/'+file)
 
maxPage=int(input("how many pages:"))
# 產生一run.bat,  再執行run.bat檔
inputstr = input("paste here:")
 
inputstr = inputstr.replace("AgencyDepartment=^%^E4^%^B8^%^AD^%^E5^%^B8^%^82", "AgencyDepartment=中市")
inputstr = inputstr.replace("--compressed","")
inputstr = inputstr.replace("-H \"Accept-Encoding: gzip, deflate, br, zstd\"","")
 
runFile = open("run.bat","w")
 
#取關鍵字Index/\d  截斷, 再重新組成curl 需要的網址
for i in range(1,maxPage+1):
    fileName = str(i)+".html"
    command = re.split(r'Index\/\d', inputstr)[0] + "Index/" + str(i) + re.split(r'Index\/\d', inputstr)[1] + " -o ./tmp/" + fileName
    print(command)
    runFile.write(command)
    runFile.write("\n")
    runFile.write("timeout 2")
    runFile.write("\n")
 
runFile.close()
 
print("done")


END

你可能感興趣的文章

python+curl 爬資料(一) 需要某網站資料抓回來統計,結果當然沒我想的那麼簡單, 程式跑一跑就撈回來 光這裡就卡好久, 後來觀察cookie 從 c

python 的RE python re

找尋多個文件夾中最新檔案(jpg,png,txt)並複製到nexus資料夾 找尋多個文件夾中最新檔案(jpg,png,txt)並複製到集中資料夾

python 解析資料, 輸入並輸出 database, csv, pdf(二) 延續上篇 https://n.sfs.tw/content/index/16452 parse html class B

00-F2 的 IPV6 反解設定 近日, 強者我的大神同事, line 傳來一句: igogo 上次你那個ipv6的設定檔 再幫我跑一次 如連結 程式都寫

隨機好文

vue.js components 多個組件的呈現 vue.js 組件 component

vue.js component 在parent與child 傳值 component 在parent與child 傳值

Google sheet 建立成績單的總分及排名並提供名字下拉查詢 Google sheet, sum, rank, pull down list

刪除資料夾內的檔案 lambda 一行文 Arrays.stream(new File("/folder/path").

openldap資料移到 docker 拉docker 上的 image 回來 docker pull osixia/openldap 在正在運行的openld